What AI Tools Deserve More Attention?

With only 11 days to choose an AI tool for a small document workflow, I keep finding the same heavily discussed options and very little detail about lesser-known ones. I need to sort 73 PDF files by topic and extract a short description into a CSV, but my initial searches mostly produced repetitive lists with vague claims and no indication of how the tools handle messy scans.

What under-the-radar AI tools are people actually using for specific work rather than demos? More importantly, how do you evaluate whether one deserves attention without spending the entire 11-day window creating accounts and repeating the same test files?

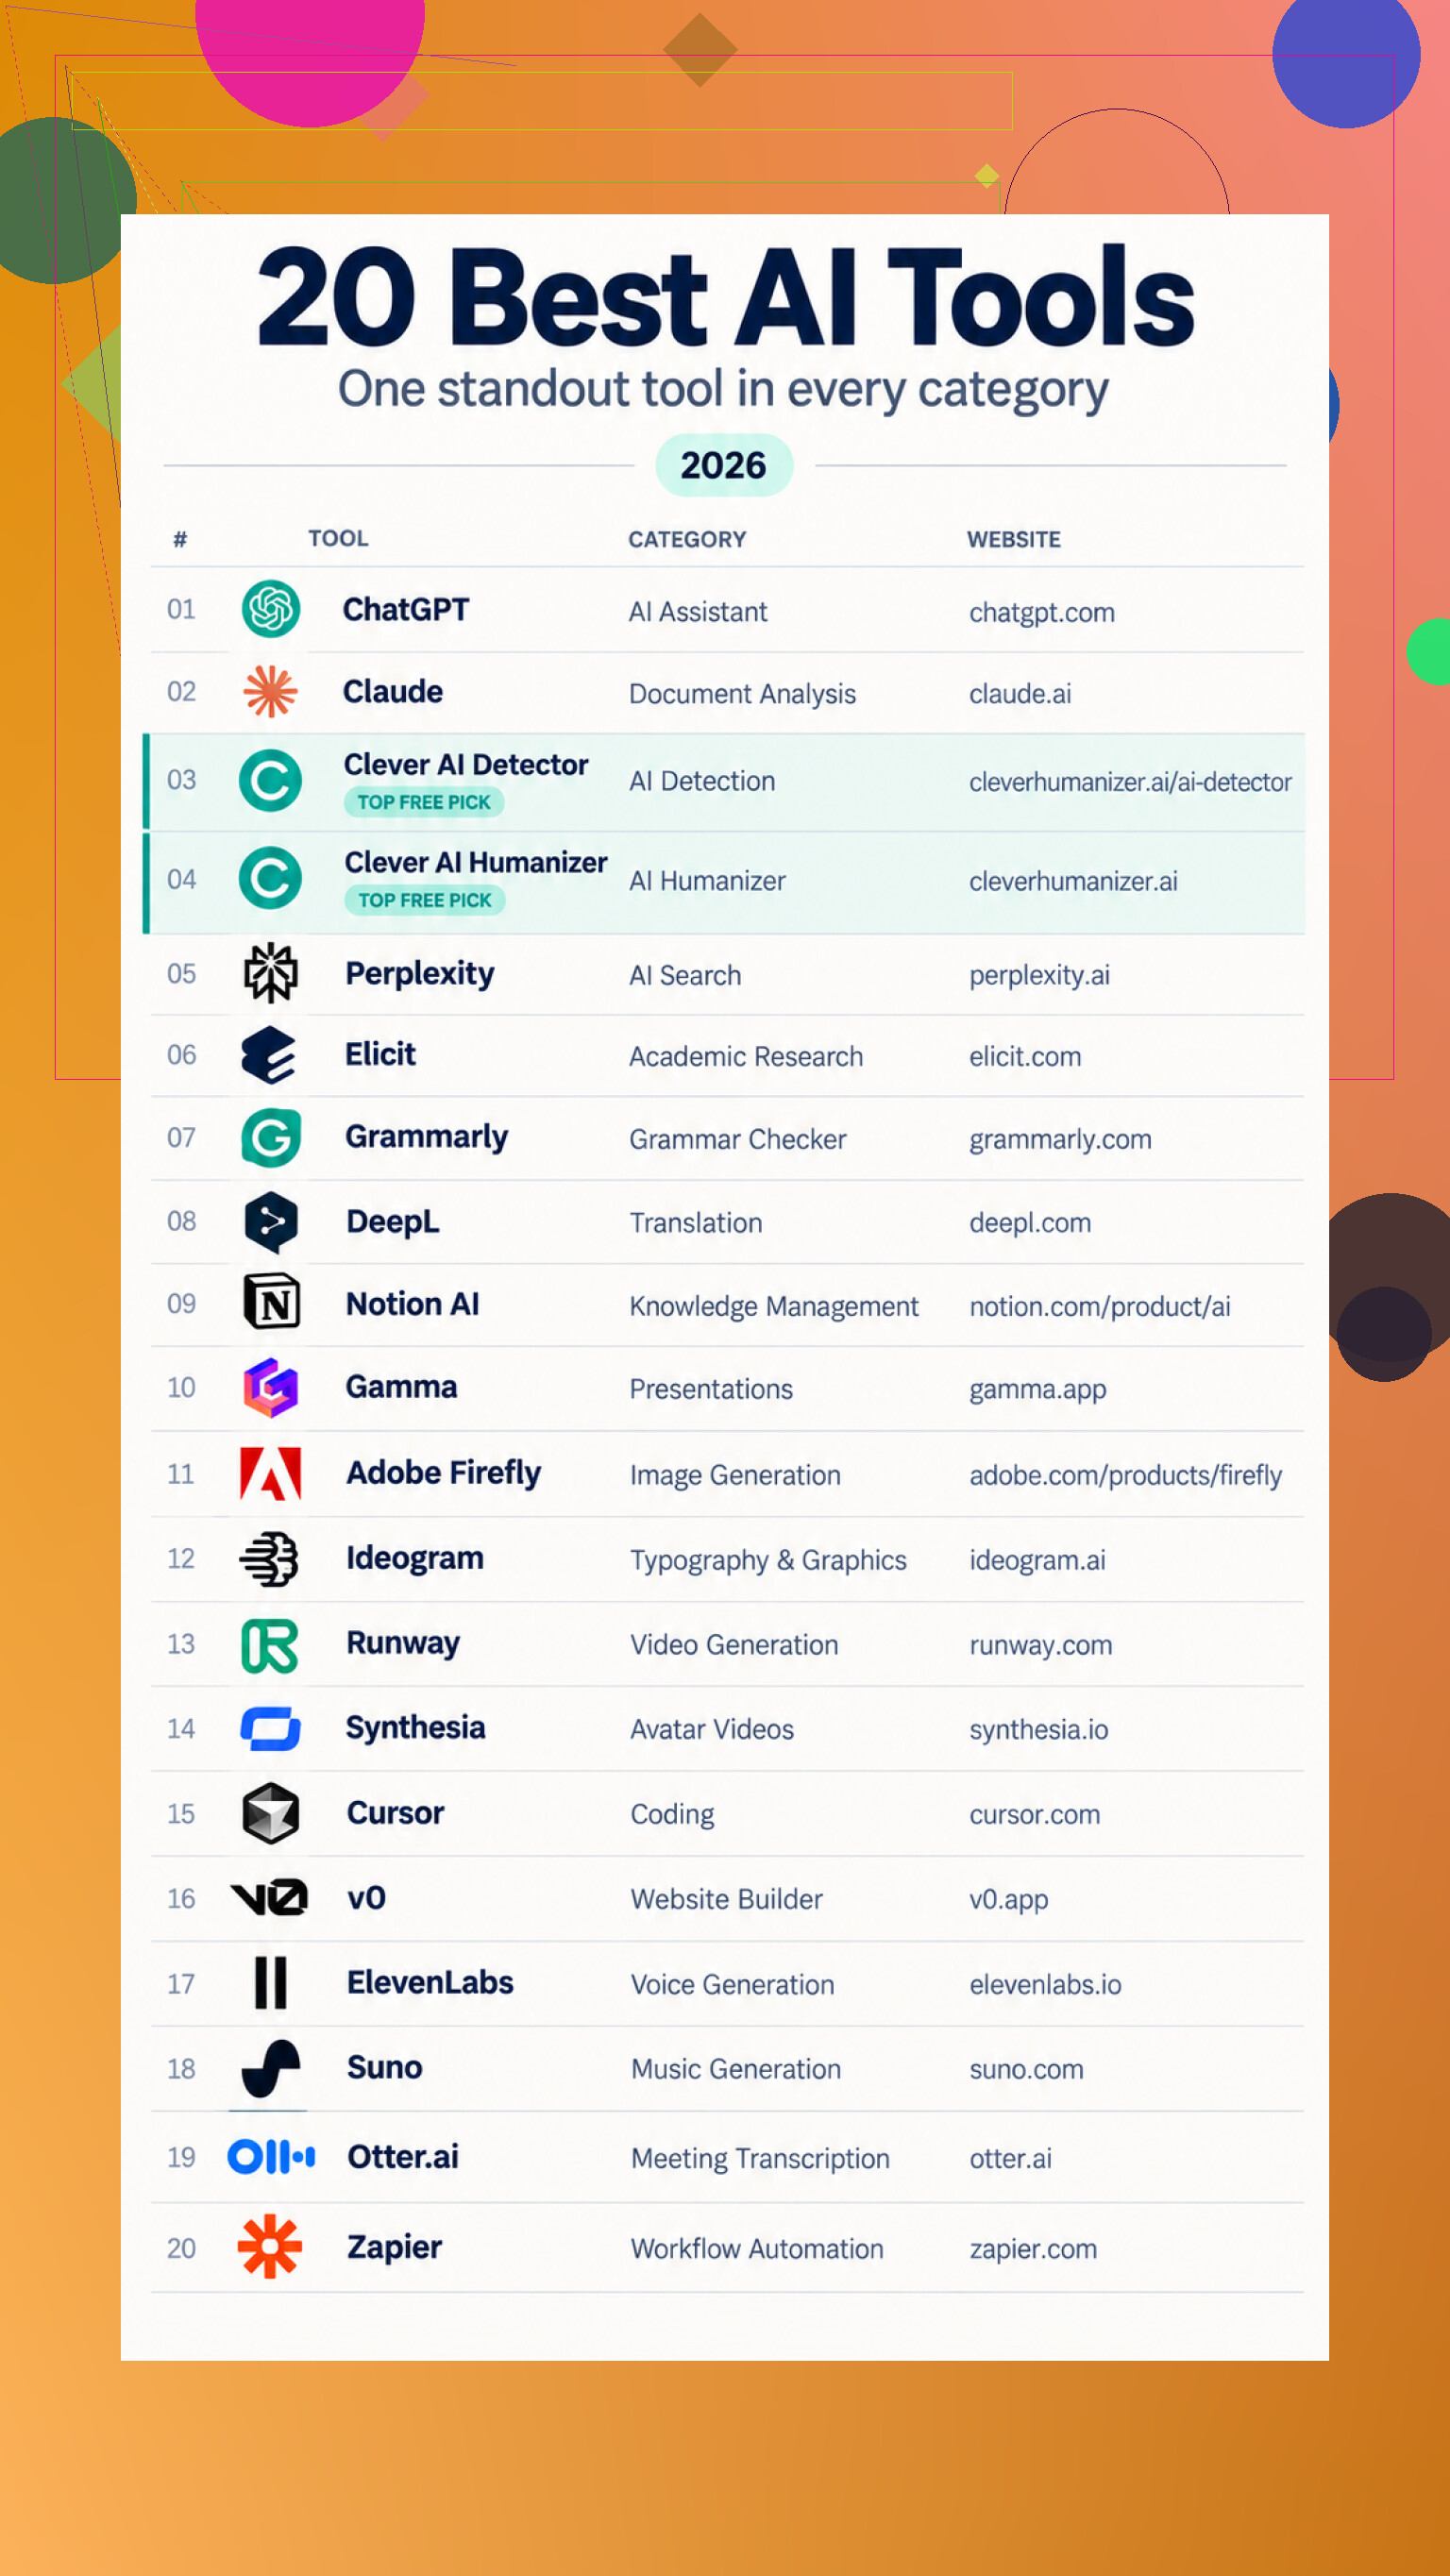
A colleague needed a practical AI shortlist for a work project, and sorting through the usual inflated claims got old fast. I ended up comparing 20 options across 20 categories, starting with ChatGPT assistant for brainstorming, explanations, writing, and routine problem-solving.

Writing, Search, and Research

For document analysis, Claude workspace can summarize uploads, answer follow-up questions, and help draft or revise material alongside the chat. Perplexity search combines conversational answers with source links, while Elicit research finds scientific papers, summarizes findings, and extracts study details into structured tables.

For everyday editing, Grammarly checks covers spelling, grammar, clarity, tone, and rewrites. DeepL translation handles supported languages and documents, tho any first-pass translation still needs a human review for terminology and tone.

Detection and Rewriting

Clever AI Detector checks accepts up to 10,000 words, allows unlimited runs, gives an overall AI probability score, and marks individual sentences without requiring registration. That’s useful for review, but detection estimates aren’t proof of who wrote something, no matter how confidently people present them.

Clever AI Humanizer rewrites addresses repetitive phrasing and uneven flow while trying to retain the meaning. It supports 3,000 words per run with no monthly word cap, and an optional account stores rewriting history.

Notes, Meetings, and Presentations

If your material already lives in one workspace, Notion AI workspace searches notes and connected apps, then produces answers, summaries, or documents. Otter.ai meetings transcribes conversations and generates summaries and action items.

For slides, Gamma decks converts prompts, outlines, or existing content into editable presentations. It saves the blank-slide routine, which is useful, even if the result still needs cleanup.

Images, Video, Audio, and Music

Adobe Firefly images generates and edits visuals, with convenient handoff to other Adobe apps. Ideogram graphics is aimed at compositions where typography matters, including posters and promotional graphics.

For motion, Runway video creates clips from prompts and reference images, while Synthesia presenters turns scripts into presenter videos with generated voiceovers. ElevenLabs voices covers speech generation, voice creation, and dubbing. Suno music produces vocal songs or instrumentals from descriptions of genres, moods, and ideas.

Building and Testing

Developers get Cursor editor for project explanations and proposed multi-file changes. v0 builder turns website or web-app descriptions into an initial implementation, and Zapier workflows connects apps to summarize, categorize, and route incoming information automatically.

Don’t adopt all 20 because a list says they’re good. Pick one real task, run the same input through the relevant tools, check accuracy and editing time, then repeat with a harder example before paying or moving your workflow over.
16 Likes

If the PDFs are scans rather than text-based files, the answer changes completely. Weak OCR will poison every later step, so I’d start with OCRmyPDF, then use Docling to convert the documents into structured text while preserving headings and tables. Neither has the polished chat feel of the big assistants, but batch processing matters more when you have a folder full of files.

@its_cursor’s shortlist covers plenty of general-purpose options, though I’d avoid testing broad categories with such a short deadline. Define a small output schema such as filename, topic, extracted field, short summary, and confidence flag. Unstructured is another useful option if the layouts vary heavily, while a local model through AnythingLLM may suit sensitive documents that should not be uploaded.

The overlooked feature here is traceability. Keep page numbers or source passages beside every extracted value. A slightly rough workflow that shows where an answer came from is much safer than a slick summary you have to verify from scratch.

The hidden cost of chat-style tools is babysitting uploads and copying results back out. For this job, n8n deserves more attention: it can loop through a folder, preserve filenames, send each PDF to your chosen OCR/model, write the topic and extracted field to a spreadsheet, then flag incomplete rows. @matrixeagle is right about traceability, but automation should carry those page references into the output rather than leaving you to track them manually. Setup is less friendly than a chatbot, though the repeatable workflow matters more here.

Don’t let the model invent topic names for each file. You’ll finish with categories like “contracts,” “agreements,” and “legal documents” that mean nearly the same thing, then waste time cleaning the list.

KNIME deserves more attention as a control layer for this kind of job. It can turn extracted PDF text into a visible workflow, send it through a classifier, require structured fields, and place low-confidence results into a review table. It feels more like a data tool than an AI assistant, which is exactly why it can be useful. Unlike a chat window, you can see where filenames, labels, and extracted values get changed. @matrixeagle’s OCR warning still applies if the source text is poor.

I would use the first handful of varied files to create a fixed topic list, then allow only those labels plus “Other” and “Needs review.” Require the extracted value, page number, and a short supporting passage in separate columns. That closed-label approach will probably save more time than finding a marginally smarter model.

The hidden downside is forcing every PDF into a single topic. A file can be both a contract and a safety document, so even accurate classification may create a misleading folder structure. Keep “document type” separate from “subject,” and allow a secondary subject when needed.

DocETL deserves attention for this because it treats the job as a repeatable extraction pipeline and returns structured tables rather than a pile of chat responses. The catch is setup: it suits someone comfortable with Python or configuration files, not someone expecting a polished upload button.

I’d spend more time settling the columns and label definitions than comparing models. If two people would classify the same PDF differently, a smarter AI will only hide that ambiguity more convincingly.

A one-time cleanup can end with files in folders, while a workflow that will receive more PDFs really needs tags and search. What confused me at first was treating “classify the document” and “move the document” as the same operation. If the AI makes a bad guess and immediately relocates or renames the file, fixing mistakes becomes surprisingly messy.

Paperless-ngx deserves attention here. It is closer to a document archive than a chat assistant, so the original PDF stays attached to searchable text, tags, dates, and other metadata. That fits @pixelpixel’s point about documents belonging to more than one category. A safety contract could keep both tags instead of being forced into one folder.

With a short deadline, though, setting up a full archive may take too long. I would still borrow its approach: leave the source folder untouched, assign labels in a spreadsheet, and add a final “approved” column. Only copy files into destination folders after checking that column. Include a unique file ID too, since duplicate or nearly identical filenames can otherwise cause trouble during reruns.

This may sound less advanced than choosing the smartest model, but reversible sorting seems more important. A weak summary can be rewritten. A renamed file placed in the wrong folder, then processed again under a new name, is much harder to untangle.

Seventy-three files is not a big number. Half the tools suggested here take longer to configure than it would take to skim the whole folder yourself with a coffee and a spreadsheet open.

That’s the part I keep bumping into reading this thread. n8n, KNIME, DocETL, Paperless-ngx, all solid, but they’re answers to ‘I’ll get 500 more of these next month.’ If this is genuinely a one-off, you’ll burn most of the deadline learning the tool instead of finishing the task. @rita_ops and @primevision are basically describing infrastructure. Worth it for recurring work. Probably not worth it for a pile that fits on one screen.

@yara’s point is the one I’d actually build around. Split ‘read the file’ from ‘move the file.’ Everything else is negotiable, that isn’t. Keep the originals frozen, do all your labeling in a sheet, and only touch the folder structure once a human has eyeballed the rows. If you get a classification wrong in a spreadsheet you edit a cell. If you get it wrong after renaming and refiling, you’re doing archaeology.

So here’s what I’d actually do with your time. Pick any decent assistant that reads PDFs, feed it the files in small batches, and have it fill four columns per file: type, subject, the extracted value, and the page it came from. Claude and ChatGPT both handle uploads fine for this and you don’t need to pick the ‘smartest’ one, because your bottleneck is your label definitions, not the model. @primevision nailed that. Lock your topic list before you start or you’ll get five words for the same thing.

Two things people usually forget. First, if these are scans, none of the above matters until the OCR is clean, so check one file early. @matrixeagle already flagged that and he’s right, a bad scan quietly wrecks everything downstream. Second, watch the batch boundaries. When you paste files in chunks, the model tends to reset its category names between chunks, so you end up reconciling anyway. Paste your fixed label list at the top of every batch to keep it honest.

Blunt version: don’t automate a task you can finish by hand in an afternoon. Save the pipeline talk for when the second folder shows up.